
Memory Bottlenecks Hinder AI Infrastructure as Inference Surpasses Training
As artificial intelligence (AI) infrastructure evolves, memory bottlenecks are emerging as a costly challenge, particularly as inference demand outpaces that of training. Graphics Processing Units (GPUs) often remain idle, waiting for data, while high-bandwidth memory (HBM) is tethered to processors that cannot adequately share it.
Marvell Technology Inc. is exploring photonics as a potential solution to these issues. The company is integrating optics with photonic memory, extending memory capabilities beyond the confines of individual chips. This advancement promises to enhance efficiency within data centers, where businesses have already invested significantly, according to Preet Virk, senior vice president and general manager of the Photonic Fabric Business Unit at Marvell.
“In the data center today, we have a lot of room for improvement of efficiency,” Virk stated. “When I refer to efficiency, I’m highlighting the wasted flops due to low GPU utilization.”
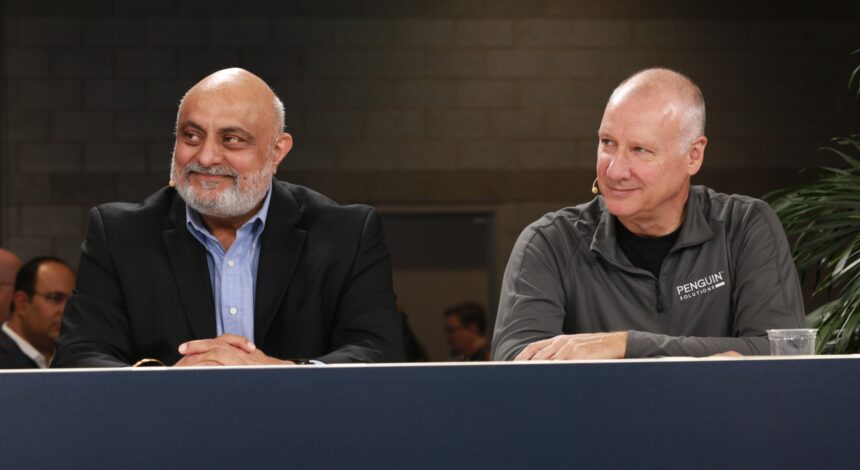
During a recent discussion at the SC26 conference, Virk and Andy Mills, vice president of advanced product development at Penguin Solutions Inc., explained how photonics and shared memory pools could alleviate memory bottlenecks in AI infrastructure. The conversation was part of an exclusive broadcast on theCUBE, SiliconANGLE Media’s livestreaming platform.
Penguin’s MemoryAI Photonic Appliance Targets Memory Limitations
Penguin Solutions has introduced the MemoryAI Photonic Appliance, designed to separate HBM into a distinct unit located tens of meters away from the GPU, connected by Marvell’s Photonic Fabric. Each appliance boasts 16 terabytes of HBM and DDR5 memory, allowing multiple servers across different racks to share this resource, Mills elaborated.
“The key challenge is ensuring your large language model (LLM) remembers the context of the conversation without losing track after 10 minutes,” Mills noted. “To achieve this, one requires a substantial amount of memory with extensive token lengths.”
The optical technology also transforms the energy efficiency equation. While copper connections suffice within a rack, transitioning data across a pod of thousands of GPUs necessitates optics, as emphasized by Virk. “More than 80 percent of scale-up network traffic comprises memory transactions, and enabling a shared pool means that much of this data remains static,” he explained.
“Within data movement, memory transactions are a critical area to scrutinize,” Virk added. “By adopting this solution in place of copper-based data movement, we can reduce energy consumption to a quarter of the picojoules per bit required for data movement.”
As AI agents demand an increasing number of token requests, surpassing even human users, Mills believes that shared pools present a pragmatic solution to address memory bottlenecks. “Distributed systems inherently support sharing because recomputing data is inefficient,” he concluded. “The success of key-value (KV) caching highlights the importance of eliminating redundant computations. When data can be shared across a broader base and across more racks, overall efficiencies improve.”