
The Rise of AI Inference and Its Economic Impact
AI inference is increasingly shaping the economics of the ongoing AI boom. While the early adoption of GPU clouds was primarily driven by training, the future will hinge on the swift and cost-effective serving of AI models.
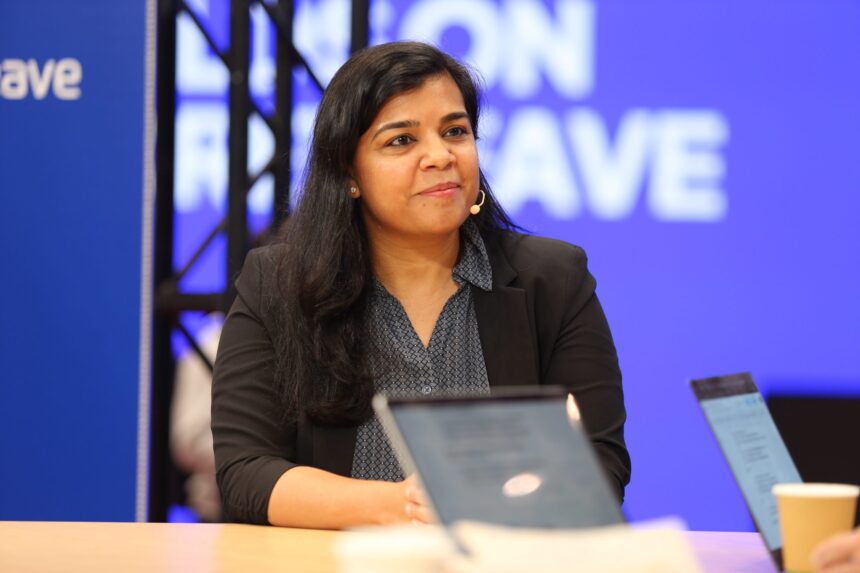
This transition is prompting specialized cloud providers to expand their focus beyond mere GPU capacity, venturing into storage, networking, and software solutions. CoreWeave Inc. is taking significant steps in this direction by offering managed services for training, post-training, and inference, as highlighted by Urvashi Chowdhary, the company’s Vice President of Product and AI Services.
“From an AI developer’s perspective, the goal is to solve problems as quickly as possible while ensuring optimal performance and scalability at a manageable cost,” Chowdhary explained. “Our approach centers on enhancing every layer of our stack. We are building a reliable infrastructure that allows us to provide increasingly sophisticated managed services across all phases of AI development.”
Chowdhary elaborated during a discussion with theCUBE Research’s Dave Vellante and John Furrier at the Fully Connected event, which was broadcast live from theCUBE, a SiliconANGLE Media platform. The conversation covered topics including AI inference, managed services across the entire stack, and CoreWeave’s RL Rollouts, a newly introduced feature aimed at accelerating the iteration of agentic models.
Enhancing AI Inference Through Focused Optimizations
The demand for AI inference is surging rapidly. A recent survey conducted by theCUBE Research revealed that one healthcare client’s share of inference workload escalated from around 10% in the first year to 40% in the second year, with expectations of reaching 50% within the upcoming year. In response, CoreWeave is fine-tuning each layer of its architecture, from the vLLM engine to quantized models and custom speculative decoders, as per Chowdhary’s insights.
She emphasized, “Our strategy has been to intentionally leverage open-source tools and technologies, contributing back to open ecosystems, which grants our customers increased flexibility. We are also committed to developing our services in a layered approach.”
As reinforcement learning becomes more prevalent, challenges have arisen. When clients train agentic models using rewards and verification processes, inference can become a bottleneck during rollouts. To address this, CoreWeave’s RL Rollouts capability—developed on Nvidia’s Dynamo framework—facilitates the integration of new checkpoints into an active deployment. Testing has shown that this functionality can significantly reduce model reload latency, improving it by 15 times compared to standard configurations.
These new functionalities reside within CoreWeave Forge, a recently launched platform designed to integrate serving, observability, post-training, and evaluation processes. Forge offers a free-tier option to get started, while paid tiers provide extended functionalities, ensuring that even individual developers have access to superior AI development tools and services.
The full interview is available as part of SiliconANGLE and theCUBE’s coverage of the Fully Connected event.